Use VCE Exam Simulator to open VCE files

100% Latest & Updated Microsoft Azure Data DP-900 Practice Test Questions, Exam Dumps & Verified Answers!
30 Days Free Updates, Instant Download!
DP-900 Premium Bundle
Microsoft DP-900 Practice Test Questions, Microsoft DP-900 Exam Dumps
With Examsnap's complete exam preparation package covering the Microsoft DP-900 Practice Test Questions and answers, study guide, and video training course are included in the premium bundle. Microsoft DP-900 Exam Dumps and Practice Test Questions come in the VCE format to provide you with an exam testing environment and boosts your confidence Read More.
Microsoft DP-900 remains the current Azure Data Fundamentals exam. The July 21, 2026 blueprint covers core data concepts, relational data on Azure, non-relational data on Azure, and analytics workloads. It is a fundamentals exam, but candidates still need to understand why different data models and services exist rather than memorize product names.
DP-900 is designed for people beginning to work with data in the cloud. It does not require deep administration or development experience, and it is not a prerequisite for later Microsoft credentials. Its value is conceptual: it gives candidates a vocabulary for transactional versus analytical workloads, relational versus non-relational storage, batch versus streaming, and the way Azure services map to those needs. Microsoft certifications become much easier to navigate once those distinctions are clear.
The most effective preparation uses small examples. Model the same business data in a relational table, a document store, and an analytical structure. Then ask which queries each representation makes easy, which constraints it preserves, and what type of workload it is intended to serve. DP-900 rewards that kind of comparison more than feature memorization.
Operational systems usually optimize for frequent inserts, updates, and point lookups, while analytical systems aggregate large volumes of historical data. Those patterns influence data shape, indexing, consistency, latency expectations, and the services that fit best. A point-of-sale transaction and a quarterly sales trend may use the same business facts but have very different technical requirements.
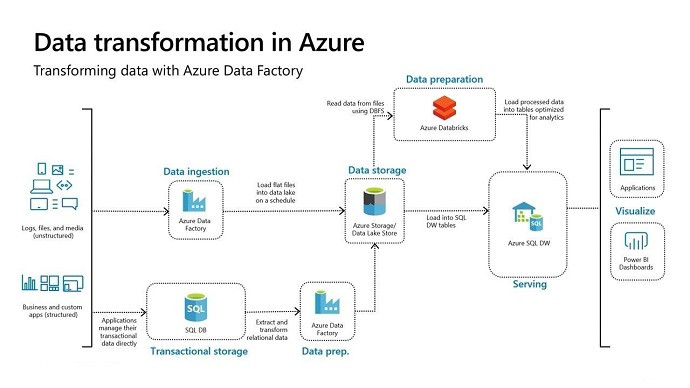
Sketch a simple retail system with orders, customers, inventory, and daily reporting. Identify which operations need immediate consistency and which can run after data is accumulated. The source-to-dashboard analytics flow helps show why data often moves through several stages before it becomes a decision-ready metric.
Relational systems organize data into tables with rows, columns, keys, and relationships. Primary keys identify records, foreign keys connect tables, and normalization can reduce duplication. SQL provides a declarative way to query and modify the model. ACID transactions are important when a set of changes must succeed or fail together.
Create customers and orders tables with a foreign-key relationship, then write a query that joins them. Add a transaction that updates inventory and inserts an order. If one step fails, roll the transaction back. These exercises make relational concepts tangible before candidates encounter Azure SQL products.
Document, key-value, graph, and column-oriented systems address workloads that do not always fit normalized tables. Flexible schema, horizontal distribution, and access patterns can be more important than joins. The relational, NoSQL, columnar, and object-storage models is useful because it ties storage models to workload behavior rather than treating one model as universally superior.
Represent a product catalog as relational rows and as self-contained JSON documents. Consider how each design handles varying product attributes, updates, filtering, and reporting. The point is not to choose NoSQL because it sounds modern; it is to recognize when the shape and scale of the workload justify it.
Azure SQL Database, Azure SQL Managed Instance, and SQL Server on Azure virtual machines all support relational workloads, but they differ in platform management, compatibility, operating-system access, patching, high availability, and migration effort. A managed service reduces infrastructure responsibility, while a virtual machine preserves more control.
Take an existing SQL Server application that depends on instance-level features and compare migration choices. Then imagine a new cloud-native application with no legacy dependencies. The appropriate destination may change because the constraints changed. Fundamentals-level understanding means recognizing those tradeoffs without needing to administer every feature.
Azure Cosmos DB is designed for low-latency, horizontally distributed operational applications and supports flexible document-oriented data. Partitioning, consistency, and globally distributed reads and writes are central concepts. A DP-900 candidate does not need DP-420-level development depth, but should understand why a service like Cosmos DB fits workloads that need scale and flexible data models.
Compare a globally distributed user-profile service with a traditional single-region relational application. Ask what happens when traffic grows unevenly, when users are far from the database, or when schema varies. Candidates who later move into DP-420 will deepen these ideas into partition keys, indexing, SDK behavior, and resilience.
Azure Storage services can hold blobs, files, queues, and tables, each with different access patterns. Object storage is especially important in analytics because raw files, logs, media, and exported datasets may be stored cheaply before they are transformed. File format also matters: CSV, JSON, and columnar formats such as Parquet behave differently for analytical processing.
Place a small dataset in CSV and Parquet and compare file size and analytical scan behavior conceptually. The Azure data storage types are easier to remember when each service is connected to a concrete kind of data rather than a product list.
Modern analytics often involves ingestion, transformation, lake or warehouse storage, semantic modeling, and visualization. Azure and Microsoft Fabric provide services that cover those stages. Candidates should understand the difference between collecting data, transforming it, querying it analytically, and presenting it to business users.
Trace a web-application log from source to a dashboard. Identify where data is collected, cleaned, stored, modeled, and visualized. Then distinguish the role of a data engineer from an analyst. This makes later credentials such as Fabric Data Engineer Associate and Fabric Analytics Engineer easier to place.
Batch processing works on accumulated data at intervals; streaming or real-time processing handles events as they arrive or with very low delay. Neither is automatically better. The business question determines whether a daily aggregate, a five-minute window, or an immediate alert is necessary.
Use an IoT example: daily energy usage may be a batch report, while an overheating alert needs near-real-time processing. Consider event ingestion, windowing, and downstream action at a conceptual level. DP-900 questions often become straightforward when the timing requirement is identified first.
Create ten short scenarios and choose a data approach for each: relational transactions, flexible documents, large analytical scans, file storage, dashboards, and streaming telemetry. For every answer, write one sentence explaining why the chosen model fits and one reason an alternative would be weaker.
The DP-900 exam domains is most useful after this exercise because it can reveal which concepts still require explanation. The exam is a test of data judgment at the fundamentals level: recognize the workload, understand the model, and map the requirement to an appropriate service family.
Candidates should be able to separate descriptive, diagnostic, predictive, and prescriptive analytics at a conceptual level. A dashboard that reports last month’s revenue is different from a model that predicts churn, even if both use the same customer data. Write one business question for each analytics type and identify what additional data or processing it would require. This prevents the word “analytics” from becoming a catch-all label that hides fundamentally different workloads.
Data roles are also worth distinguishing. Database administrators protect and operate databases; data engineers build and maintain data flows; analysts model and interpret data for decisions; data scientists build statistical or machine-learning models. Real teams overlap, but the center of responsibility differs. Understanding that separation helps explain why DP-300 database administration, DP-700 data engineering, and DP-600 analytics engineering exist as different role-based paths after the fundamentals level.
Structured, semi-structured, and unstructured data should be tied to examples. A SQL row with fixed columns is structured; JSON with varying attributes is semi-structured; images and free-form documents are unstructured. The categories influence storage and processing choices but do not dictate a single service. Many real systems combine all three, such as an ecommerce platform with relational orders, JSON product metadata, and product images in object storage.
Data governance can be introduced without turning DP-900 into a compliance exam. Ask who owns a dataset, who may read it, how long it should be retained, and how consumers know it is trustworthy. Those questions apply regardless of whether the data sits in a relational database, a lakehouse, or object storage. The data governance and lineage concepts explain why discovering and understanding data is part of analytics architecture.
Cost and scale should be considered qualitatively. A service that is perfect for a few thousand transactions may not be ideal for petabytes of analytical scans, while a distributed analytical platform can be unnecessarily complex for a small transactional application. Recognize whether the requirement emphasizes low-latency transactions, flexible schema, massive aggregation, or streaming arrival before thinking about individual Azure products.
Close preparation by explaining each major DP-900 concept without vendor jargon. Describe what makes data relational, why a key-value or document model exists, what distinguishes batch from streaming, why an analytics system differs from an operational database, and where storage fits. If those explanations remain clear before Azure service names are added, you have the conceptual foundation the exam expects.
Practice the language of scale as well: vertical scaling changes the resources of one system, while horizontal scaling spreads work across multiple resources or partitions. At the fundamentals level, candidates do not need to engineer every scaling mechanism, but they should recognize why distributed services exist and why partitioning appears in non-relational systems. Connecting scale to workload shape is more useful than memorizing which Azure service has a particular button.
ExamSnap's Microsoft DP-900 Practice Test Questions and Exam Dumps, study guide, and video training course are complicated in premium bundle. The Exam Updated are monitored by Industry Leading IT Trainers with over 15 years of experience, Microsoft DP-900 Exam Dumps and Practice Test Questions cover all the Exam Objectives to make sure you pass your exam easily.
Purchase Individually


DP-900 Training Course

SPECIAL OFFER: GET 10% OFF
This is ONE TIME OFFER

A confirmation link will be sent to this email address to verify your login. *We value your privacy. We will not rent or sell your email address.
Download Free Demo of VCE Exam Simulator
Experience Avanset VCE Exam Simulator for yourself.
Simply submit your e-mail address below to get started with our interactive software demo of your free trial.