


Use VCE Exam Simulator to open VCE files

Get 100% Latest Microsoft Certified: Azure Data Engineer Associate Practice Tests Questions, Accurate & Verified Answers!
30 Days Free Updates, Instant Download!
Microsoft Certified: Azure Data Engineer Associate Certification Practice Test Questions, Microsoft Certified: Azure Data Engineer Associate Exam Dumps
ExamSnap provides Microsoft Certified: Azure Data Engineer Associate Certification Practice Test Questions and Answers, Video Training Course, Study Guide and 100% Latest Exam Dumps to help you Pass. The Microsoft Certified: Azure Data Engineer Associate Certification Exam Dumps & Practice Test Questions in the VCE format are verified by IT Trainers who have more than 15 year experience in their field. Additional materials include study guide and video training course designed by the ExamSnap experts. So if you want trusted Microsoft Certified: Azure Data Engineer Associate Exam Dumps & Practice Test Questions, then you have come to the right place Read More.
Microsoft Certified: Azure Data Engineer Associate is now a legacy credential. Microsoft retired both the certification and DP-203 on March 31, 2025, so new candidates can no longer earn it. That does not make the old blueprint useless. DP-203 covered a durable set of engineering problems: moving data into analytical platforms, transforming it at scale, choosing batch or streaming patterns, securing data stores, and monitoring pipelines after deployment.
The important 2026 distinction is between studying a retired certification for historical skill context and following a current certification path. Microsoft’s closest modern data-engineering route is Microsoft Certified: Fabric Data Engineer Associate, with DP-700 centered on Microsoft Fabric. Candidates who still encounter DP-203 material should use it to understand transferable engineering concepts, then deliberately translate those concepts into Fabric rather than preparing as if the old exam were still available.
That transition is more than a product rename. Azure Synapse Analytics, Azure Data Factory, Azure Databricks, data lakes, security, orchestration, and observability shaped the older role. Fabric reorganizes many analytical workloads into a more integrated platform. A strong learning plan therefore keeps the engineering principles and updates the service context.
The original certification expected candidates to design and implement data storage, develop processing, secure and monitor data solutions, and optimize workloads. That breadth forced engineers to think beyond a single pipeline. A technically correct ingestion job could still be a poor design if it ignored partitioning, lineage, access control, recovery, or operational cost. The role was about building a dependable analytical system rather than merely copying records from one service to another.
This is why the retired credential still appears in job histories and older training plans. Organizations continue to run workloads built during the DP-203 era, and many of the operational questions remain current. Engineers still need to reason about schema drift, late-arriving data, idempotent loading, orchestration dependencies, and performance bottlenecks. The certification itself is retired, but those problems did not retire with it.
Another durable lesson from DP-203 is that data engineering sits inside a wider platform. Pipelines depend on identity, networking, storage, compute quotas, naming standards, and deployment controls. An engineer who understands only transformation code can be blocked by service limits or weak environment design. That is why the old role often collaborated with administrators, database specialists, security teams, and analysts: the pipeline was one component in a larger operating system for data.
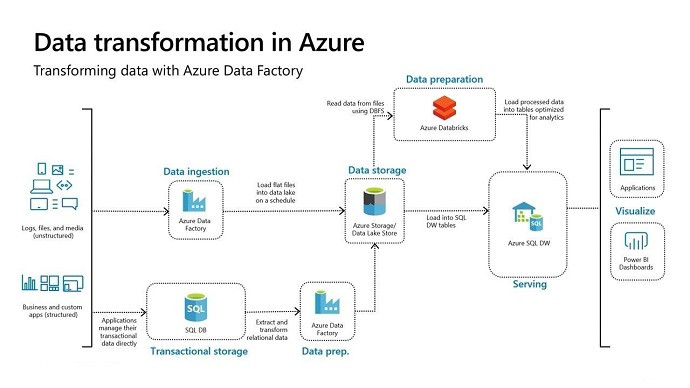
Older Azure estates also commonly combine Synapse, Data Factory, Databricks, and storage accounts rather than using one perfectly standardized service. Candidates maintaining those systems should learn how boundaries were chosen and where responsibility lives. That historical context makes modernization safer because teams can distinguish a component that is merely old from one whose architecture genuinely creates cost, security, or reliability problems.
A useful data engineer starts by understanding how data is produced. Transactional databases, files, APIs, event streams, SaaS platforms, and telemetry have different latency, ordering, retry, and consistency characteristics. The older Azure role used services such as Data Factory and Synapse pipelines, but the deeper skill is captured by data-pipeline architecture: decide how data arrives, how it is validated, where failures are isolated, and how downstream systems know what is complete.
Batch ingestion favors completeness and throughput, while streaming favors low latency and continuous state. The trade-off is not simply fast versus slow. Streaming can introduce ordering, replay, checkpointing, and operational complexity that a nightly batch does not need. A mature engineer chooses the simplest pattern that satisfies the business requirement and adds complexity only where the value of lower latency justifies it.
DP-203 emphasized lake, warehouse, and analytical storage decisions because storage layout affects every later stage. File formats, partition keys, compression, retention, and table organization influence query cost and performance. Engineers also need to separate raw data from curated outputs so that transformation mistakes can be corrected without losing the original source. Those ideas remain useful whether the platform is Synapse, Databricks, Fabric, or another modern analytical stack.
A good storage design also anticipates multiple consumers. Data scientists may need detailed history, analysts may need governed dimensional models, and operational applications may need low-latency aggregates. Forcing every workload into one representation usually creates friction. The better pattern is controlled reuse: preserve authoritative data, publish fit-for-purpose models, and document how each layer was derived.
Transformations are not only technical conversions. Renaming fields, joining entities, deduplicating records, calculating measures, and handling slowly changing dimensions encode business rules. If those rules are hidden inside unreviewed notebook logic, the platform becomes hard to trust. Engineers should make assumptions visible, test edge cases, and separate reusable transformation logic from one-off exploration.
The same principle applies when choosing SQL, Spark, Python, or low-code transformation tools. A tool is appropriate when it matches the data volume, team skills, deployment model, and maintenance burden. The old exam rewarded familiarity with several engines, but experienced engineers learn to choose deliberately instead of defaulting to whichever service is most fashionable.
Real-time processing introduces questions that batch workflows can postpone. What happens when events arrive late? Can the same event be processed twice? How are windows defined? What if a consumer falls behind? The distinction between batch and streaming data processing is therefore architectural, not cosmetic. The engineer needs a recovery story as well as a happy path.
DP-203-era services exposed candidates to event ingestion, Spark streaming, and analytical processing. In 2026, the products may evolve, but the mental model remains valuable: define event identity, checkpoint progress, make processing replay-safe, and monitor end-to-end lag. A streaming platform that cannot be replayed or reconciled safely will eventually turn a small incident into a data-quality problem.
Data engineering often creates broad technical access because pipelines must read from sources and write to multiple stores. That makes least privilege, managed identities, secrets management, encryption, and network controls essential. Governance is equally important: teams need to know who owns a dataset, which fields are sensitive, what transformations occurred, and whether the data is appropriate for a particular use.
The older curriculum introduced cataloging and governance ideas that now appear across modern platforms. Data governance, catalogs, and lineage are useful because they connect engineering to accountability. A successful pipeline is not merely one that completes; it is one whose output can be discovered, explained, secured, and trusted.
Pipelines fail because source schemas change, quotas are reached, credentials expire, upstream files are late, or compute behaves differently under real load. Monitoring therefore needs more than a green success icon. Teams should capture duration, data volume, freshness, retry counts, failed partitions, and quality checks so that degradation can be detected before users report missing data.
Operational maturity also includes controlled deployment. Changes to pipelines, notebooks, schemas, and infrastructure should move through version control and predictable environments. When teams can reproduce a data platform from code and configuration, recovery is faster and audits are clearer. That lesson transfers directly into current Fabric engineering, where Git integration, deployment pipelines, and repeatable workspace configuration matter.
Data quality deserves its own operational signal. A pipeline can finish with no exception while quietly producing duplicates, missing partitions, invalid reference keys, or implausible measures. Mature teams define expectations around completeness, uniqueness, ranges, and reconciliation, then surface failures early. This is especially important when many downstream dashboards or models depend on one shared dataset, because a small upstream defect can be amplified across the organization.
The current DP-600 versus DP-700 distinction helps explain Microsoft’s modern data roles. Fabric Data Engineer focuses on ingestion, transformation, orchestration, lakehouse and warehouse engineering, streaming, security, and operational management. Fabric Analytics Engineer is closer to semantic models, analytical solutions, and consumption. That separation is clearer than treating every data professional as one generic “Azure data” role.
A DP-203 holder moving forward should map old strengths deliberately. Strong orchestration and Spark skills transfer well, but Fabric introduces OneLake, Fabric workspaces, Dataflow Gen2, Eventstreams, and other platform conventions. The correct transition is not to relearn data engineering from zero; it is to reapply durable concepts inside the current service model.
Someone maintaining older Synapse and Data Factory estates can still gain real value from DP-203 objectives because they describe the systems already in production. Someone pursuing a new credential in 2026 should not spend months rehearsing a retired exam. The practical route is to review the old blueprint for gaps, then move into the current Fabric path and hands-on projects that prove the same engineering judgment on today’s tools.
The broader Microsoft certifications inventory now offers more specialized paths across Fabric, Databricks, AI, database administration, and architecture. Azure Data Engineer Associate remains useful as a historical marker of how Microsoft defined the role, but the strongest candidate treats it as context for the present rather than a credential that can still be earned.
Study with ExamSnap to prepare for Microsoft Certified: Azure Data Engineer Associate Practice Test Questions and Answers, Study Guide, and a comprehensive Video Training Course. Powered by the popular VCE format, Microsoft Certified: Azure Data Engineer Associate Certification Exam Dumps compiled by the industry experts to make sure that you get verified answers. Our Product team ensures that our exams provide Microsoft Certified: Azure Data Engineer Associate Practice Test Questions & Exam Dumps that are up-to-date.

Microsoft Training Courses





SPECIAL OFFER: GET 10% OFF
This is ONE TIME OFFER

A confirmation link will be sent to this email address to verify your login. *We value your privacy. We will not rent or sell your email address.
Download Free Demo of VCE Exam Simulator
Experience Avanset VCE Exam Simulator for yourself.
Simply submit your e-mail address below to get started with our interactive software demo of your free trial.
