


Use VCE Exam Simulator to open VCE files

Get 100% Latest Microsoft Certified: Fabric Data Engineer Associate Practice Tests Questions, Accurate & Verified Answers!
30 Days Free Updates, Instant Download!
Microsoft Certified: Fabric Data Engineer Associate Certification Practice Test Questions, Microsoft Certified: Fabric Data Engineer Associate Exam Dumps
ExamSnap provides Microsoft Certified: Fabric Data Engineer Associate Certification Practice Test Questions and Answers, Video Training Course, Study Guide and 100% Latest Exam Dumps to help you Pass. The Microsoft Certified: Fabric Data Engineer Associate Certification Exam Dumps & Practice Test Questions in the VCE format are verified by IT Trainers who have more than 15 year experience in their field. Additional materials include study guide and video training course designed by the ExamSnap experts. So if you want trusted Microsoft Certified: Fabric Data Engineer Associate Exam Dumps & Practice Test Questions, then you have come to the right place Read More.
Microsoft Certified: Fabric Data Engineer Associate is a current intermediate credential in Microsoft certifications and is earned through DP-700. Microsoft defines the role around data loading patterns, data architectures, orchestration, security, monitoring, and optimization using SQL, PySpark, and KQL across Microsoft Fabric.
Microsoft lists an English-language certification update for October 19, 2026. On October 2, the current outline still applies, so candidates should prepare from today’s domains while reviewing the published change information if their exam is scheduled after that date.
DP-700 is not simply “DP-600 with more code.” Fabric analytics engineering and data engineering divide ownership differently: the data engineer owns movement, transformation, storage, orchestration, and operational reliability, while the analytics engineer concentrates more on analytical assets, semantic models, and consumption. That boundary also affects permissions, deployment ownership, monitoring responsibilities, and the troubleshooting evidence each role is expected to interpret.
A Fabric data engineer should be able to choose among lakehouse, warehouse, event-oriented, and other data patterns based on volume, velocity, structure, query needs, ownership, and downstream consumers. The architecture has to support both the initial load and the years of operation that follow.
Understanding lakehouse and warehouse architecture helps because storage is not an isolated choice. It affects transformation tools, access methods, governance, query performance, schema management, and how easily teams can reuse the data.
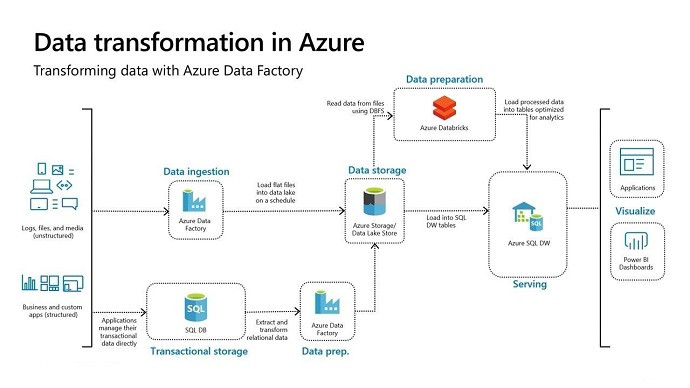
Candidates should practice drawing data flows before building them. Identify sources, landing zones, transformations, curated outputs, consumers, failure points, and security boundaries. That exposes design problems earlier than experimenting directly in production-like workspaces.
Data can arrive through batch files, databases, APIs, event streams, shortcuts, replication, or other connectors. A successful first load proves very little. Production ingestion must handle re-runs, late data, schema changes, partial failure, duplicate delivery, and source outages.
A good data pipeline architecture defines checkpoints and ownership. Engineers should know which step is safe to repeat, how high-water marks are stored, how failed records are isolated, and how operators determine whether a daily or hourly delivery is complete.
Credentials and network access are also part of ingestion. Connections should use appropriate identities and secrets, not personal accounts embedded in code. The operational model should survive staff changes and environment promotion.
DP-700 candidates work with SQL, PySpark, notebooks, pipelines, and dataflows. The important skill is not preferring one tool; it is placing transformation logic where it is maintainable, observable, and efficient for the workload.
Transformations should include validation. Schema checks, null rules, duplicate detection, referential checks, reconciliation totals, and business constraints help prevent bad data from moving silently into curated layers. A pipeline that completes successfully can still produce an incorrect dataset.
Engineers should also separate technical normalization from business modeling where possible. That allows analytical teams to reuse clean, stable data while keeping business-specific metrics in the appropriate semantic layer.
A layered data design can help separate raw capture, standardized data, and curated business-ready outputs, but the names of the layers matter less than the contracts between them. Engineers should know which layer is replayable from source, where data quality rules become mandatory, and which tables downstream consumers are allowed to depend on.
Schema evolution needs explicit handling. Sources add columns, change types, or introduce new codes over time. Pipelines should either accommodate compatible changes or fail visibly when a change would corrupt downstream assumptions. Silently accepting a breaking schema can produce the most dangerous kind of incident: a green pipeline with wrong data.
Tool choice should follow the workload. SQL is often ideal for relational transformations and warehouse logic; PySpark is useful for distributed processing and code-oriented transformation; KQL is powerful for event and time-series analysis. DP-700 candidates should be able to explain why a transformation belongs in one engine instead of selecting a language only because it is familiar.
Pipelines and scheduling coordinate dependencies, retries, branching, parameters, and environment-specific settings. Candidates should understand how to design a workflow so a failed upstream load does not allow dependent transformations to publish incomplete results.
Concurrency is another concern. Running more tasks in parallel can reduce elapsed time but may overwhelm sources, compute, or downstream stores. Engineers should know which activities can execute independently and which require serialized ordering.
Operational metadata is valuable. Capturing run identifiers, source timestamps, row counts, durations, and error states makes troubleshooting faster and enables trend analysis across repeated runs.
Event streams and real-time analytics operate continuously rather than in discrete nightly batches. Engineers need to think about event time, arrival time, windows, late events, ordering, duplication, throughput, and retention. A design that works for static files may not make sense for an event stream.
KQL and event-oriented storage help query time-series and operational data, but data quality still matters. Bad events can arrive faster than a human can investigate them, so validation and monitoring need to be automated.
Candidates should practice scenarios such as a source disconnect, a sudden volume spike, or a schema change. The goal is to understand how the pipeline degrades and how service can be restored without losing or double-counting data.
A unified lake can reduce unnecessary copies, and shortcuts can expose data across locations without traditional duplication. That changes the architecture question from “How do we move this file?” to “Do we need to move it at all?”
Engineers still need to understand access, ownership, performance, and lifecycle. Referencing data in place can create dependency on an external owner or source service. The consuming team needs to know what availability and schema guarantees exist.
Good designs document which data is copied, referenced, cached, transformed, or materialized and why. That clarity helps with cost, performance, troubleshooting, and governance.
Workspace access, item permissions, OneLake security, identities, and governed data ownership determine who can see and change analytical assets. The broader discipline of data governance and lineage should be designed into pipelines from the beginning.
Least-privilege service identities reduce risk. Engineers should avoid using powerful human accounts for automated processes and should separate development, deployment, and runtime responsibilities where possible.
Lineage helps both governance and operations. When a source changes, teams should be able to identify affected downstream pipelines, tables, models, and reports quickly.
A production data solution needs visibility into pipeline success, duration, data freshness, capacity usage, query performance, Spark jobs, and failure patterns. Without baselines, teams cannot tell whether a slower run is normal variation or an emerging incident.
Optimization should target the bottleneck actually observed. Partitioning, file sizes, query shape, Spark configuration, warehouse design, concurrency, and transformation logic can all affect performance. Changing several variables at once makes the result difficult to interpret.
Cost and performance are related. More compute can hide inefficient design, while aggressive cost reduction can create unacceptable latency. Engineers need service-level expectations so optimization has a measurable target.
Recovery planning should include more than retrying one failed activity. Teams need to know how to replay a window of data, rebuild a corrupted table, recover from a bad transformation deployment, and reconcile outputs after an outage. Those procedures should be tested before a critical reporting deadline exposes the weakness.
Cost observability is increasingly important in shared Fabric environments. Engineers should understand which jobs consume compute, when scaling or scheduling changes help, and how inefficient Spark, SQL, or orchestration patterns can create recurring cost. Optimization is strongest when it improves both service reliability and resource efficiency.
Build an end-to-end workload: ingest data, transform it with SQL or PySpark, publish it to a lakehouse or warehouse, orchestrate the process, secure the environment, and monitor a few runs. Then connect it to the Fabric Analytics Engineer side to see how the engineered data becomes a semantic or reporting asset.
Create failure drills. Change a schema, duplicate input, break a credential, delay a source, or introduce a poor partitioning choice. Repairing those failures develops the diagnostic ability that real data engineering requires.
Finally, compare the Microsoft study guide again if the exam occurs after October 19, 2026. The current certification is active, but its English objectives are scheduled to change, and preparation should follow the version in effect on the actual test date.
Add a deployment step to the lab so configuration and code move through at least two environments. Parameters, connections, workspace references, and identities should change through controlled configuration rather than manual edits. That exposes the lifecycle issues that appear only after a solution becomes shared infrastructure.
The final practice should include an operational handoff: document the pipeline schedule, dependencies, freshness expectation, alert path, and recovery steps as though another engineer had to support the system. DP-700 is ultimately about reliable data engineering, and reliability includes making the platform understandable to people other than its original builder.
Study with ExamSnap to prepare for Microsoft Certified: Fabric Data Engineer Associate Practice Test Questions and Answers, Study Guide, and a comprehensive Video Training Course. Powered by the popular VCE format, Microsoft Certified: Fabric Data Engineer Associate Certification Exam Dumps compiled by the industry experts to make sure that you get verified answers. Our Product team ensures that our exams provide Microsoft Certified: Fabric Data Engineer Associate Practice Test Questions & Exam Dumps that are up-to-date.

Microsoft Training Courses



SPECIAL OFFER: GET 10% OFF
This is ONE TIME OFFER

A confirmation link will be sent to this email address to verify your login. *We value your privacy. We will not rent or sell your email address.
Download Free Demo of VCE Exam Simulator
Experience Avanset VCE Exam Simulator for yourself.
Simply submit your e-mail address below to get started with our interactive software demo of your free trial.
